ICLR 2027, under review
Seongchan Kim김성찬
Integrated M.S.–Ph.D. student at CVLAB, Kim Jaechul Graduate School of AI, KAIST, advised by Prof. Seungryong Kim.
I study how intelligent systems perceive dynamic scenes and act within them. I started with multimodal video understanding and generation, and now work on vision-language-action models for autonomous driving and robot manipulation.
Next, I want to understand world models and action generation: how well perception, context modeling, and action generation inside a world model can capture the uncertainty of future dynamics.
Publications* equal contribution
Under review
ICLR 2027, under review
PLAYGROUND: Progressive Layout Generation with Render-Grounded Planning
ICLR 2027, under review
DreamX: Video Diffusion Model is a Universal Latent Action Learner
CVPR 2027, under review
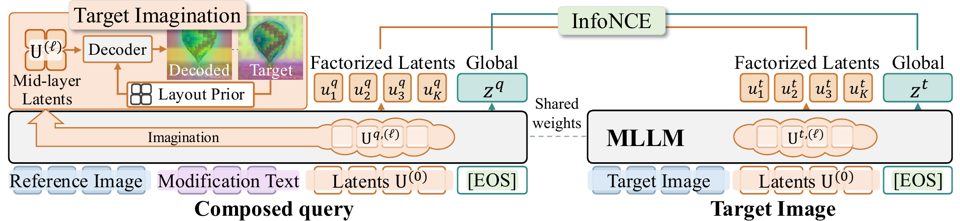
Factorized MLLM Embeddings for Composed Image Retrieval
Conference
Workshop
ODI, PTA and VLM4RWD Workshops at NeurIPS 2026
One Loss Is Not Enough: Cross-Objective Structured Pruning for Reasoning Vision–Language–Action Models
Preliminary version of the ICLR 2027 submission on driving VLA pruning.
AdaptFM Workshop at ICML 2026
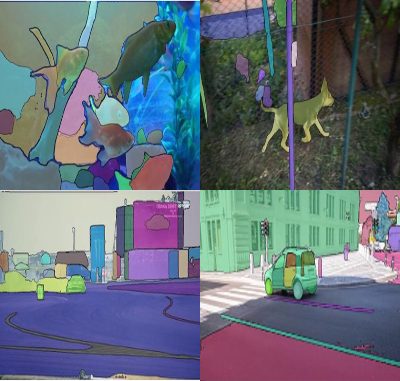
Referring Video Object Segmentation via Language-Aligned Track Selection
Research experience
May 2026 – now
Efficient autonomous driving models
LG Innotek, industry–academia project at CVLAB, KAIST
Proposed an analysis-driven structured pruning method for reasoning driving VLAs (Alpamayo) that cuts memory and inference latency while preserving performance (ICLR 2027, under review).
Jan – Mar 2026
Research intern
Maum AI, WORV Research Team
Researched vision-language-action models for robot manipulation that take long-context inputs, using input token compression for the underlying multimodal LLM.
Dec 2024 – Nov 2025
Visual inspection with segmentation and captioning models
Samsung Electro-Mechanics, industry–academia project at CVLAB, KAIST
Combined segmentation and captioning models for visual inspection, and developed an interaction-aware referring video object segmentation method grounded in natural language (InterRVOS, CVPR 2026).
Background
Education
- KAIST, Integrated M.S.–Ph.D., Kim Jaechul Graduate School of AIMar 2025 – now. Advisor: Prof. Seungryong Kim
- Korea University, B.S. in Computer Science and EngineeringMar 2020 – Aug 2024
Honors
- Future Industry Graduate ScholarshipHyundai Motor Chung Mong-Koo Foundation, Mar 2025 – now
- Future Industry Undergraduate ScholarshipHyundai Motor Chung Mong-Koo Foundation, Sep 2023 – Aug 2024
Service
- Conference reviewerICLR 2027, AAAI 2026 and 2027
Contact
- star._.overflow@kaist.ac.krOpen to research collaborations and internships.